
GeneralBearishCoinDesk · Mar 297/10
AI Pulse News
Models, papers, tools. 110,094 articles with AI-powered sentiment analysis and key takeaways.
110094 articles
GeneralBearishFortune Crypto · Mar 297/10

GeneralBearishFortune Crypto · Mar 287/10
GeneralBullishBlockonomi · Mar 287/10
GeneralBearishFortune Crypto · Mar 287/10
AIBullishMarkTechPost · Mar 287/10
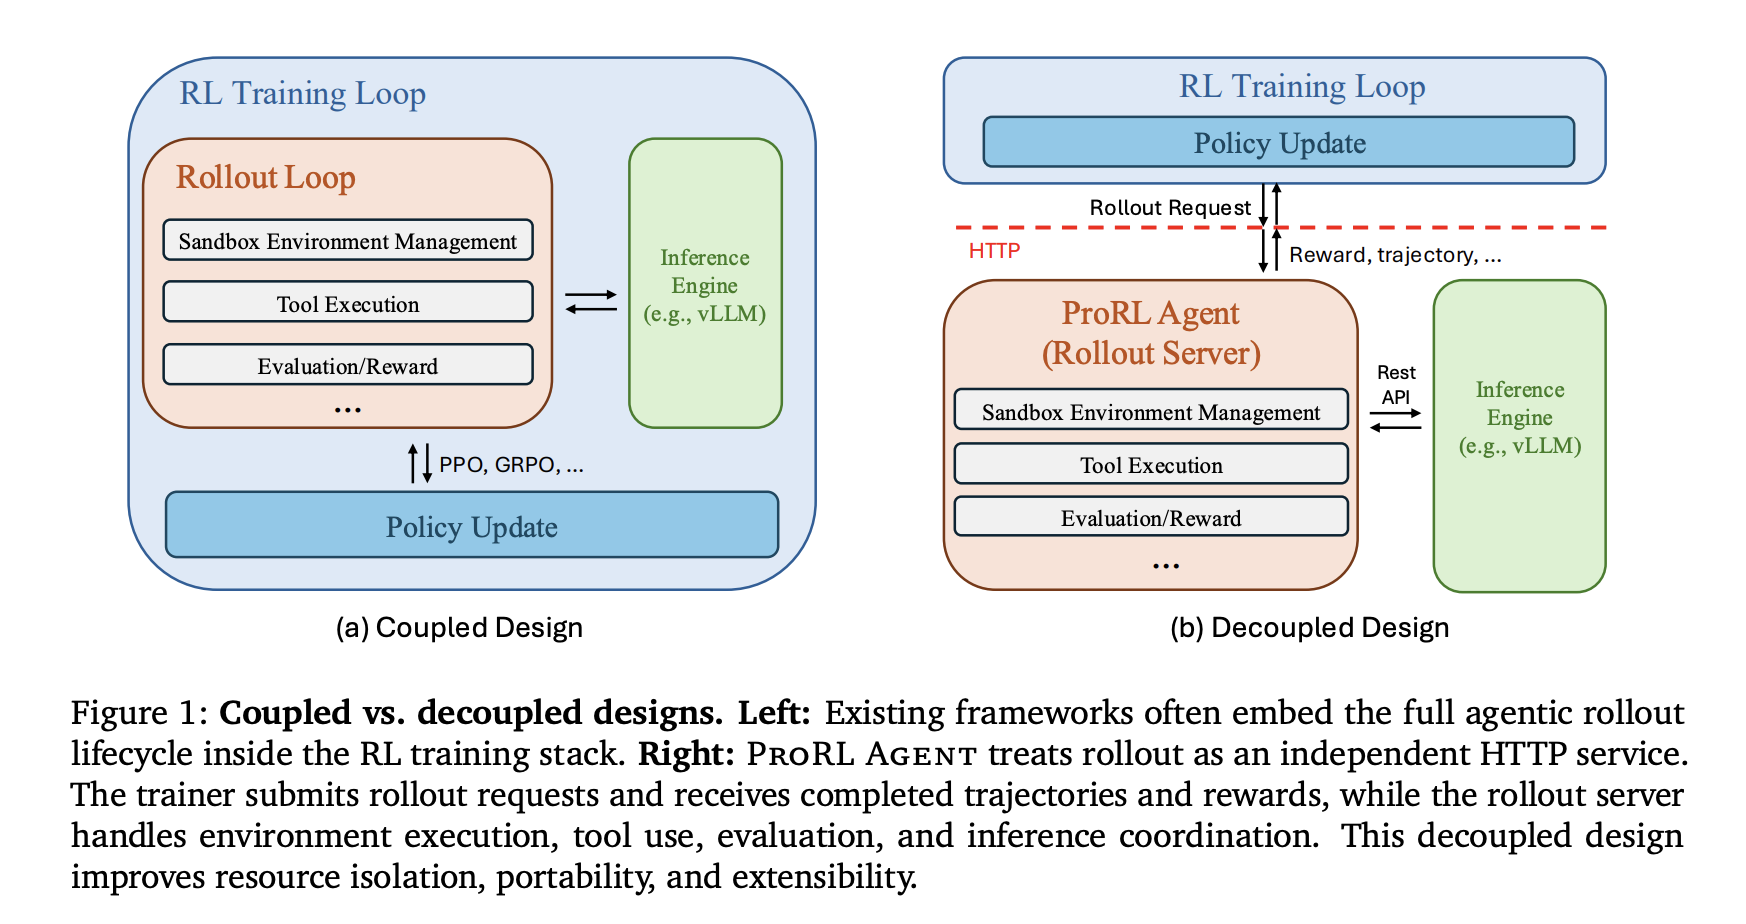
GeneralBullishCrypto Briefing · Mar 277/10

AIBearishBlockonomi · Mar 277/10
🧠
🏢 Anthropic🧠 Claude
AIBearishCoinDesk · Mar 277/10
AIBullishBlockonomi · Mar 277/10
AIBearishBlockonomi · Mar 277/10
🧠
OpenAI Sits at the Center of a $1.4 Trillion Capital Loop, Morgan Stanley Warns
Morgan Stanley warns that OpenAI sits at the center of a massive $1.4 trillion capital loop, with infrastructure commitments far exceeding its $13 billion annual revenue. Major tech companies like Microsoft, Amazon, Oracle, and Nvidia are both funding OpenAI and receiving its spending commitments back, creating potential hidden leverage risks for investors.
🏢 OpenAI🏢 Nvidia
AI × CryptoBearishcrypto.news · Mar 277/10
🤖
How to verify an exchanger: red flags, reviews, and proof points
The article discusses the rising threat of AI-powered crypto scams and fake exchanges that exploit user urgency and poor verification practices. It highlights how easily fraudulent crypto platforms can mimic legitimate exchanges to drain user funds.
AINeutralarXiv – CS AI · Mar 277/10
🧠
ARC-AGI-3: A New Challenge for Frontier Agentic Intelligence
Researchers introduce ARC-AGI-3, a new benchmark for testing agentic AI systems that focuses on fluid adaptive intelligence without relying on language or external knowledge. While humans can solve 100% of the benchmark's abstract reasoning tasks, current frontier AI systems score below 1% as of March 2026.
AIBullisharXiv – CS AI · Mar 277/10
🧠
Ming-Flash-Omni: A Sparse, Unified Architecture for Multimodal Perception and Generation
Ming-Flash-Omni is a new 100 billion parameter multimodal AI model with Mixture-of-Experts architecture that uses only 6.1 billion active parameters per token. The model demonstrates unified capabilities across vision, speech, and language tasks, achieving performance comparable to Gemini 2.5 Pro on vision-language benchmarks.
🧠 Gemini
AINeutralarXiv – CS AI · Mar 277/10
🧠
DiffuGuard: How Intrinsic Safety is Lost and Found in Diffusion Large Language Models
Researchers identified critical security vulnerabilities in Diffusion Large Language Models (dLLMs) that differ from traditional autoregressive LLMs, stemming from their iterative generation process. They developed DiffuGuard, a training-free defense framework that reduces jailbreak attack success rates from 47.9% to 14.7% while maintaining model performance.
AIBullisharXiv – CS AI · Mar 277/10
🧠
DRIFT: Dynamic Rule-Based Defense with Injection Isolation for Securing LLM Agents
Researchers introduce DRIFT, a new security framework designed to protect AI agents from prompt injection attacks through dynamic rule enforcement and memory isolation. The system uses a three-component approach with a Secure Planner, Dynamic Validator, and Injection Isolator to maintain security while preserving functionality across diverse AI models.
AIBearisharXiv – CS AI · Mar 277/10
🧠
The LLM Bottleneck: Why Open-Source Vision LLMs Struggle with Hierarchical Visual Recognition
Research reveals that open-source large language models (LLMs) lack hierarchical knowledge of visual taxonomies, creating a bottleneck for vision LLMs in hierarchical visual recognition tasks. The study used one million visual question answering tasks across six taxonomies to demonstrate this limitation, finding that even fine-tuning cannot overcome the underlying LLM knowledge gaps.
AIBearisharXiv – CS AI · Mar 277/10
🧠
Epistemic Bias Injection: Biasing LLMs via Selective Context Retrieval
Researchers have identified a new attack vector called Epistemic Bias Injection (EBI) that manipulates AI language models by injecting factually correct but biased content into retrieval-augmented generation databases. The attack steers model outputs toward specific viewpoints while evading traditional detection methods, though a new defense mechanism called BiasDef shows promise in mitigating these threats.
AIBullisharXiv – CS AI · Mar 277/10
🧠
The Future of AI-Driven Software Engineering
A paradigm shift is occurring in software engineering as AI systems like LLMs increasingly boost development productivity. The paper presents a vision for growing symbiotic partnerships between human developers and AI, identifying key research challenges the software engineering community must address.
AIBearisharXiv – CS AI · Mar 277/10
🧠
LLMs know their vulnerabilities: Uncover Safety Gaps through Natural Distribution Shifts
Researchers have identified a new vulnerability in large language models called 'natural distribution shifts' where seemingly benign prompts can bypass safety mechanisms to reveal harmful content. They developed ActorBreaker, a novel attack method that uses multi-turn prompts to gradually expose unsafe content, and proposed expanding safety training to address this vulnerability.
AIBullisharXiv – CS AI · Mar 277/10
🧠
SWAA: Sliding Window Attention Adaptation for Efficient and Quality Preserving Long Context Processing
Researchers propose SWAA (Sliding Window Attention Adaptation), a toolkit that enables efficient long-context processing in large language models by adapting full attention models to sliding window attention without expensive retraining. The solution achieves 30-100% speedups for long context inference while maintaining acceptable performance quality through four core strategies that address training-inference mismatches.
AIBullisharXiv – CS AI · Mar 277/10
🧠
LLM4AD: Large Language Models for Autonomous Driving -- Concept, Review, Benchmark, Experiments, and Future Trends
Researchers have published a comprehensive review of Large Language Models for Autonomous Driving (LLM4AD), introducing new benchmarks and conducting real-world experiments on autonomous vehicle platforms. The paper explores how LLMs can enhance perception, decision-making, and motion control in self-driving cars, while identifying key challenges including latency, security, and safety concerns.
AIBullisharXiv – CS AI · Mar 277/10
🧠
Decidable By Construction: Design-Time Verification for Trustworthy AI
Researchers propose a framework for verifying AI model properties at design time rather than after deployment, using algebraic constraints over finitely generated abelian groups. The approach eliminates computational overhead of post-hoc verification by building trustworthiness into the model architecture from the start.
AINeutralarXiv – CS AI · Mar 277/10
🧠
How Pruning Reshapes Features: Sparse Autoencoder Analysis of Weight-Pruned Language Models
Researchers conducted the first systematic study of how weight pruning affects language model representations using Sparse Autoencoders across multiple models and pruning methods. The study reveals that rare features survive pruning better than common ones, suggesting pruning acts as implicit feature selection that preserves specialized capabilities while removing generic features.
🧠 Llama
AIBullisharXiv – CS AI · Mar 277/10
🧠
AD-CARE: A Guideline-grounded, Modality-agnostic LLM Agent for Real-world Alzheimer's Disease Diagnosis with Multi-cohort Assessment, Fairness Analysis, and Reader Study
Researchers developed AD-CARE, an AI agent that uses large language models to diagnose Alzheimer's disease from incomplete medical data across multiple modalities. The system achieved 84.9% diagnostic accuracy across 10,303 cases and improved physician decision-making speed and accuracy in clinical studies.