#language-models News & Analysis
Recent coverage of #language-models spans 390 articles, with 109 published in the last 30 days. Discussion has grown more measured: bullish sentiment dropped 11 percentage points over the past month, now standing at 38.5%, while neutral coverage dominates at 52.3%. Meta's Llama and OpenAI's GPT-4 appear most frequently in these discussions, alongside emerging competitors like Perplexity. Research preprints from arXiv lead source volume, reflecting the field's rapid technical development. Related conversations often touch on #machine-learning, #ai-research, and #ai-safety considerations. Scan the articles below for the latest developments.
sentiment · last 30d (109 articles) · -11pp bullish vs prior 90dTop sources:arXiv – CS AI · 300Apple Machine Learning · 2Crypto Briefing · 2OpenAI News · 2Import AI (Jack Clark) · 1
Most-discussed entities:Llama · 17GPT-4 · 8Perplexity · 5GPT-5 · 5Claude · 3
AINeutralarXiv – CS AI · May 96/10
🧠Researchers propose KLCF, a reinforcement learning framework designed to reduce hallucinations in large language models during long-form text generation by aligning a policy model's knowledge distribution with its base model's parametric knowledge. The approach uses a Dual-Fact Alignment mechanism with factual checklists and truthfulness rewards, demonstrating consistent improvements across benchmarks without requiring external retrieval.
AINeutralFortune Crypto · May 76/10
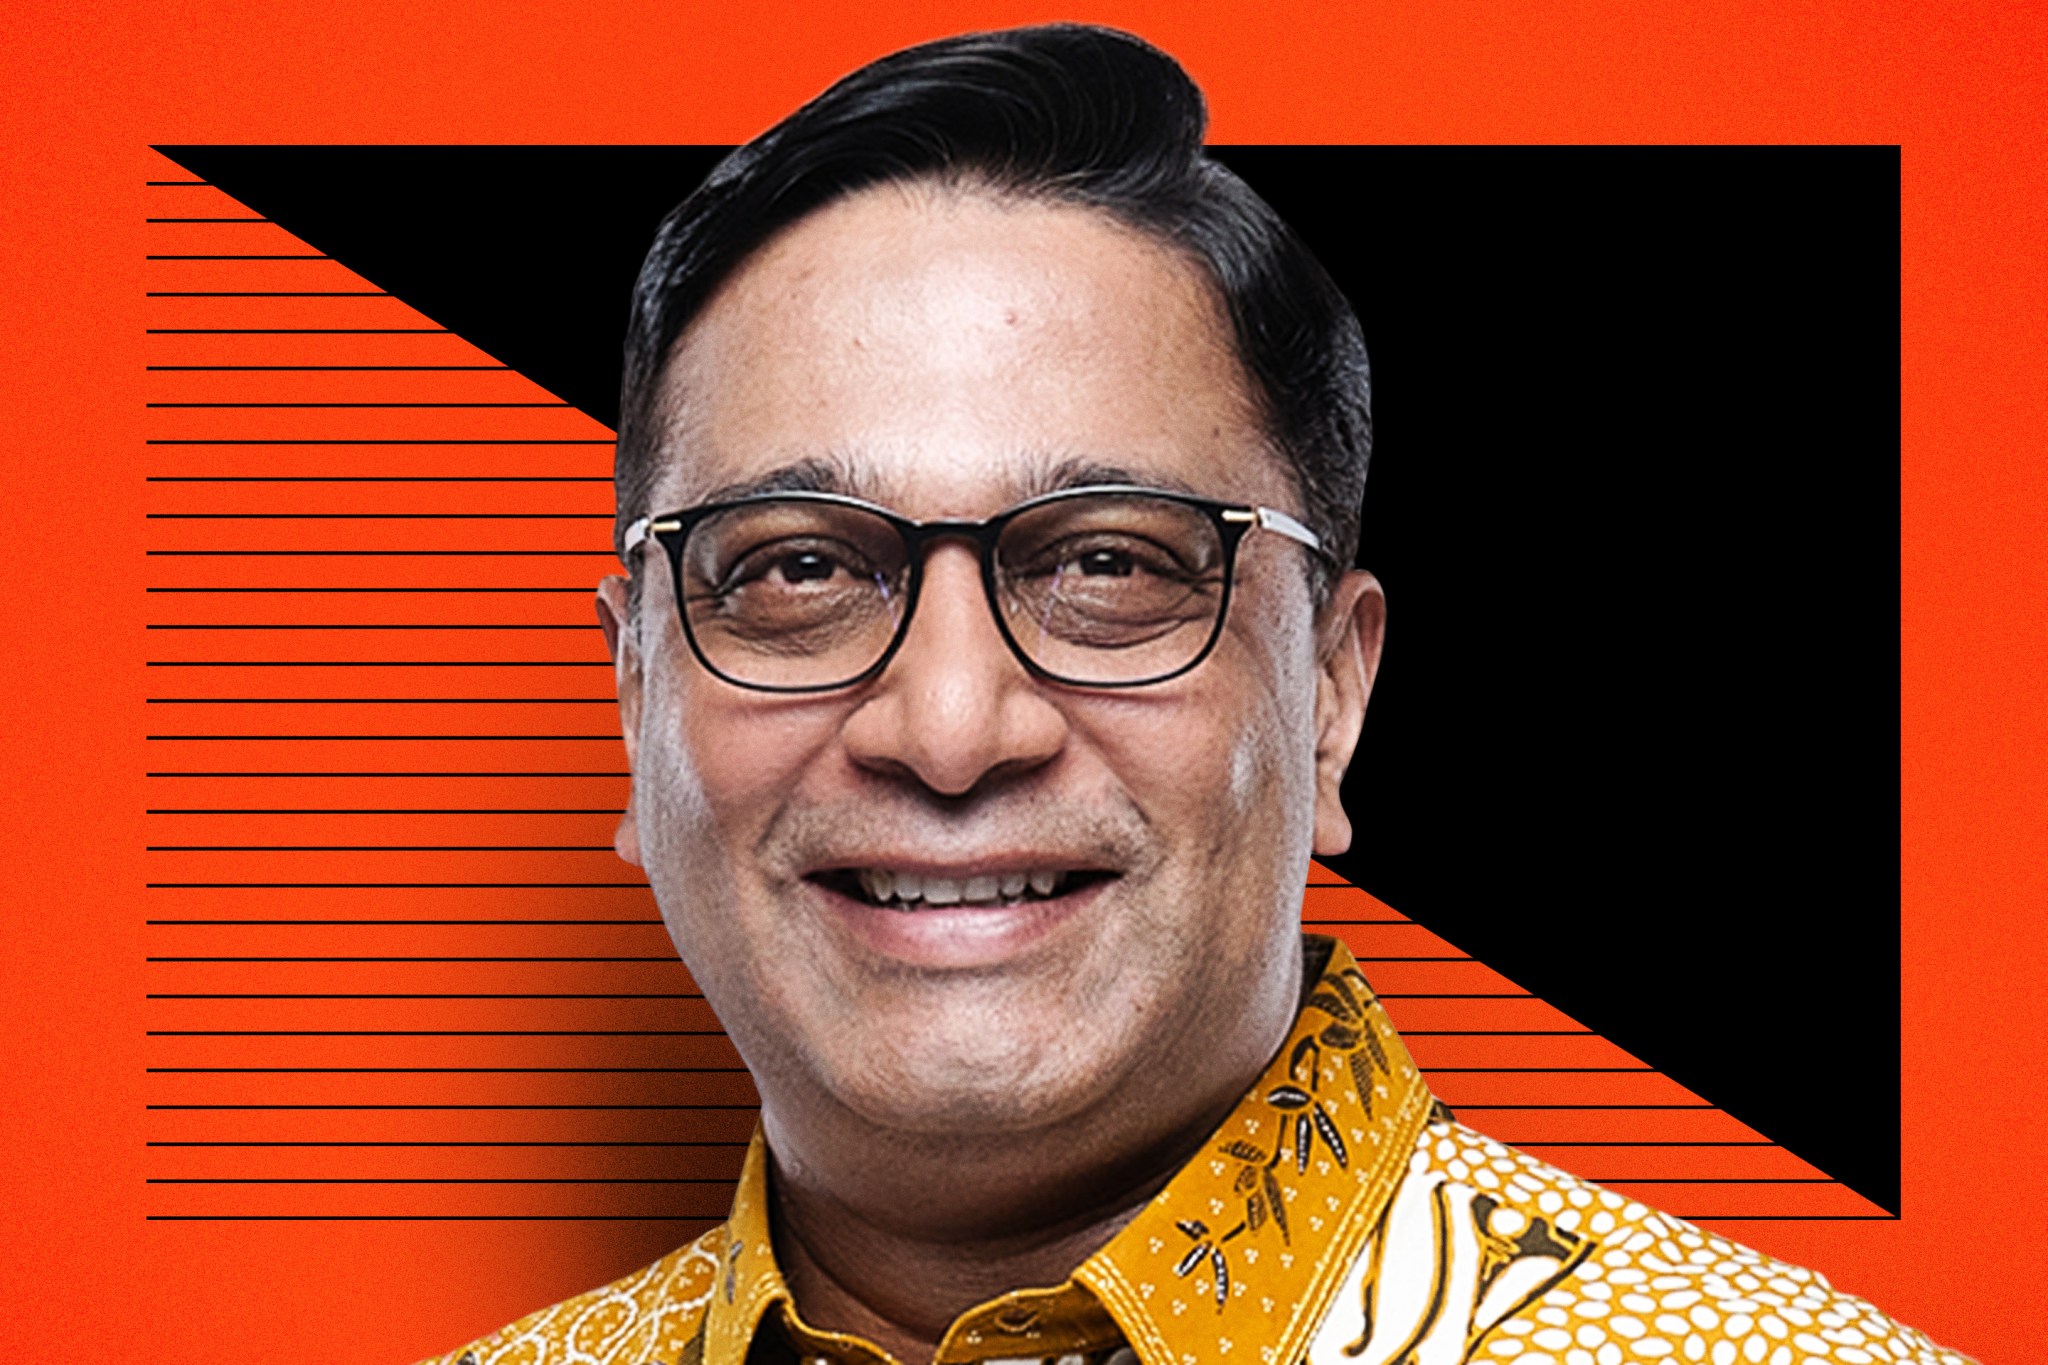
🧠Indosat CEO Vikram Sinha is developing Sahabat AI, a platform designed to support Indonesian startups building AI applications for local languages. Despite the ambitious vision for digital sovereignty, Sinha acknowledges the team currently lacks a clear commercial model, reflecting broader challenges in monetizing language-specific AI infrastructure.
AIBullishDecrypt – AI · May 76/10
🧠Google has developed Multi-Token Prediction drafters that accelerate Gemma 4 inference by up to 3x on local hardware without requiring cloud infrastructure or sacrificing output quality. This advancement makes efficient on-device AI more practical for developers and users seeking faster, privacy-preserving language model performance.
AIBullishOpenAI News · May 76/10
🧠Parloa has developed AI-powered customer service agents that leverage OpenAI's models to deliver voice-driven interactions at scale. The platform enables enterprises to design, simulate, and deploy reliable real-time customer support solutions, representing a significant advancement in conversational AI for business applications.
🏢 OpenAI
AINeutralarXiv – CS AI · May 76/10
🧠Researchers introduce Budgeted LoRA, a distillation framework that compresses large language models by treating model compression as a structured compute allocation problem. The method achieves up to 4.05x speedup in inference through selective dense component removal and adaptive low-rank allocation, controlled by a single compute budget parameter.
🏢 Perplexity
AIBullisharXiv – CS AI · May 76/10
🧠Researchers have developed methods to efficiently align language models using online natural language feedback in domains where human supervision is limited and difficult to quantify. By iteratively optimizing proxy reward models and collecting fresh expert feedback, the approach recovers 80-100% of full-supervision performance with 3-20x fewer expert samples, demonstrating significant improvements in training data efficiency.
🧠 Haiku
AINeutralarXiv – CS AI · May 76/10
🧠Researchers introduce GEM, a novel framework combining Graph Neural Networks, mixture-of-experts routing, and ReAct agents to improve Dialogue State Tracking in multi-domain conversations. The approach achieves 65.19% accuracy on MultiWOZ 2.2, substantially outperforming large language models and existing state-of-the-art methods.
AINeutralarXiv – CS AI · May 76/10
🧠Researchers introduce Gyan, a non-transformer language model designed to address hallucinations, interpretability, and computational inefficiency in current LLMs. The architecture decouples language modeling from knowledge acquisition and achieves state-of-the-art performance while prioritizing explainability and trustworthiness for mission-critical applications.
AINeutralarXiv – CS AI · May 76/10
🧠Researchers demonstrate that incorporating think-aloud verbal protocols alongside behavioral data significantly improves automated cognitive model discovery using large language models. The approach shifts discovered models toward different structural classes, revealing decision-making mechanisms invisible to behavior-only analysis, particularly in risky decision-making contexts.
AINeutralarXiv – CS AI · May 46/10
🧠Researchers introduce ArabCulture-Dialogue, a new dataset for evaluating large language models' cultural reasoning across 13 Arabic-speaking countries in both Modern Standard Arabic and regional dialects. Benchmarking reveals significant performance gaps, with LLMs consistently underperforming on dialectal Arabic compared to standardized variants, highlighting a critical blind spot in AI language model training.
AINeutralarXiv – CS AI · May 46/10
🧠Researchers introduce Caracal, a novel architecture that replaces attention mechanisms with a parameter-efficient Multi-Head Fourier module to improve LLM scalability for long sequences. The approach achieves O(L log L) complexity using Fast Fourier Transform, implements frequency-domain causal masking for autoregressive generation, and uses standard library operators for broad deployment compatibility.
AINeutralCrypto Briefing · May 26/10
🧠Anthropic's strategic initiatives may influence the competitive landscape for leading AI models, with potential ramifications for Google's market position by May. These actions could reshape US-China technology relations and influence national security policy, affecting global AI leadership dynamics.
🏢 Anthropic
AIBullisharXiv – CS AI · May 16/10
🧠Researchers introduce Ctx2Skill, a self-evolving framework that automatically discovers and refines natural-language skills for language models to better learn from complex contexts without manual annotation or external feedback. The system uses a multi-agent loop with a Challenger, Reasoner, and Judge to autonomously generate, test, and improve skills, showing consistent improvements across context learning benchmarks.
AINeutralarXiv – CS AI · May 16/10
🧠Researchers introduce LAPITHS, a framework for critically evaluating claims about AI language models' cognitive abilities, directly challenging models like CENTAUR that claim human-like cognition. The framework demonstrates that impressive AI performance doesn't necessarily indicate human-like underlying computation or genuine cognitive abilities.
AIBullisharXiv – CS AI · May 16/10
🧠Researchers propose Self-Conditioned Masked Diffusion Models (SCMDM), a post-training adaptation that improves discrete sequence generation by conditioning each denoising step on previous predictions rather than discarding them. The method achieves nearly 50% perplexity reduction on language models and demonstrates improvements across image synthesis, molecular generation, and genomic modeling without requiring architectural changes or extra computational costs.
🏢 Perplexity
AINeutralarXiv – CS AI · May 16/10
🧠Researchers propose Comet-H, an AI system that orchestrates language models to generate research software by keeping mathematical theory, code, benchmarks, and documentation synchronized. The framework addresses hallucination and desynchronization failures in LLM-driven development, demonstrating effectiveness through a portfolio of 46 research repositories, with a static-analysis tool reaching F1=0.768 performance.
AIBearisharXiv – CS AI · May 16/10
🧠Researchers discovered that when language models receive complex adversarial instructions to underperform, they abandon semantic reasoning and collapse into positional shortcuts—defaulting to single response positions up to 99.9% of the time. This reveals fundamental vulnerabilities in how instruction-tuned models handle adversarial prompts, with implications for AI safety and evaluation reliability.
🧠 Llama
AINeutralarXiv – CS AI · Apr 206/10
🧠LLMbench is a new browser-based tool that enables detailed comparative analysis of large language model outputs through side-by-side visualization and token-level probability inspection. Unlike existing quantitative comparison tools, it applies digital humanities methodology to make the probabilistic structure of LLM-generated text legible through multiple analytical overlays and visualization modes.
AINeutralarXiv – CS AI · Apr 206/10
🧠Researchers propose DALM, a Domain-Algebraic Language Model that constrains token generation through structured denoising across domain lattices rather than unconstrained decoding. The framework uses algebraic constraints across three phases—domain, relation, and concept resolution—to prevent cross-domain knowledge interference and improve factual accuracy in specialized domains.
AIBearisharXiv – CS AI · Apr 206/10
🧠Researchers discover that post-trained language models experience systematic output diversity collapse, where fine-tuning methods reduce the variety of generated responses compared to base models. This collapse is determined during training by data composition choices and cannot be fixed through inference-time adjustments, with implications for scaling methods and creative AI applications.
AINeutralarXiv – CS AI · Apr 206/10
🧠Researchers challenge the Uniform Information Density hypothesis in LLM reasoning, finding that high-quality reasoning exhibits locally smooth but globally non-uniform information flow. This counter-intuitive pattern suggests LLMs optimize differently than human communication, with entropy-based metrics effectively predicting reasoning quality across seven benchmarks.
AINeutralarXiv – CS AI · Apr 206/10
🧠Researchers introduce DASB, a comprehensive benchmark framework for evaluating discrete audio tokens across speech, audio, and music domains. The study reveals that discrete representations lag behind continuous features and require significant tuning, with semantic tokens outperforming acoustic ones, establishing standardized evaluation protocols for multimodal AI systems.
AINeutralarXiv – CS AI · Apr 206/10
🧠Researchers propose FedTSP, a federated learning method that uses pre-trained language models to generate semantically-enriched prototypes for improving model performance across heterogeneous data. The approach leverages textual descriptions of classes to preserve semantic relationships while mitigating data heterogeneity challenges in federated settings.
AINeutralarXiv – CS AI · Apr 206/10
🧠Researchers introduced RoleConflictBench, a benchmark dataset containing over 13,000 scenarios across 65 social roles designed to test whether large language models prioritize contextual cues or learned preferences when facing conflicting role expectations. Analysis of 10 leading LLMs revealed that models predominantly rely on ingrained role preferences rather than responding dynamically to situational urgency, indicating a significant gap in contextual sensitivity.
AINeutralarXiv – CS AI · Apr 206/10
🧠Researchers have created the first comprehensive Arabic Cultural QA benchmark that translates questions across Modern Standard Arabic and regional dialects, converting multiple-choice questions into open-ended formats. Testing reveals that large language models significantly underperform on dialectal content and struggle with open-ended Arabic questions, highlighting critical gaps in culturally grounded language understanding.