#machine-learning News & Analysis
Coverage of #machine-learning spans 2,608 indexed articles, with 262 pieces published in the last month. Recent discussion shows 55.7% bullish sentiment, though this represents a 5.3 percentage point decline from the previous quarter, suggesting a modest cooling in tone. Research publications dominate the discourse, particularly through arXiv's computer science and AI sections, while conversations frequently center on models and platforms including Llama, Meta, and Gemini.
Related coverage tends to intersect with #research, #ai-research, and #llm discussions. Scan the article list below to explore the latest developments and perspectives.
sentiment · last 30d (262 articles) · -5.3pp bullish vs prior 90dTop sources:arXiv – CS AI · 1922Apple Machine Learning · 14Crypto Briefing · 10MarkTechPost · 8Hugging Face Blog · 6
Most-discussed entities:Llama · 23Meta · 17Gemini · 15GPT-4 · 14GPT-5 · 13
AIBullisharXiv – CS AI · Apr 66/10
🧠Researchers introduce Contrastive Fusion (ConFu), a new multimodal machine learning framework that aligns individual modalities and their fused combinations in a unified representation space. The approach captures higher-order dependencies between multiple modalities while maintaining strong pairwise relationships, demonstrating competitive performance on retrieval and classification tasks.
AIBullisharXiv – CS AI · Apr 66/10
🧠Researchers introduce Unified Thinker, a new AI architecture that improves image generation by separating reasoning from visual generation. The modular system addresses the gap between closed-source models like Nano Banana and open-source alternatives by enabling better instruction following through executable reasoning and reinforcement learning.
AIBullishMarkTechPost · Apr 56/10
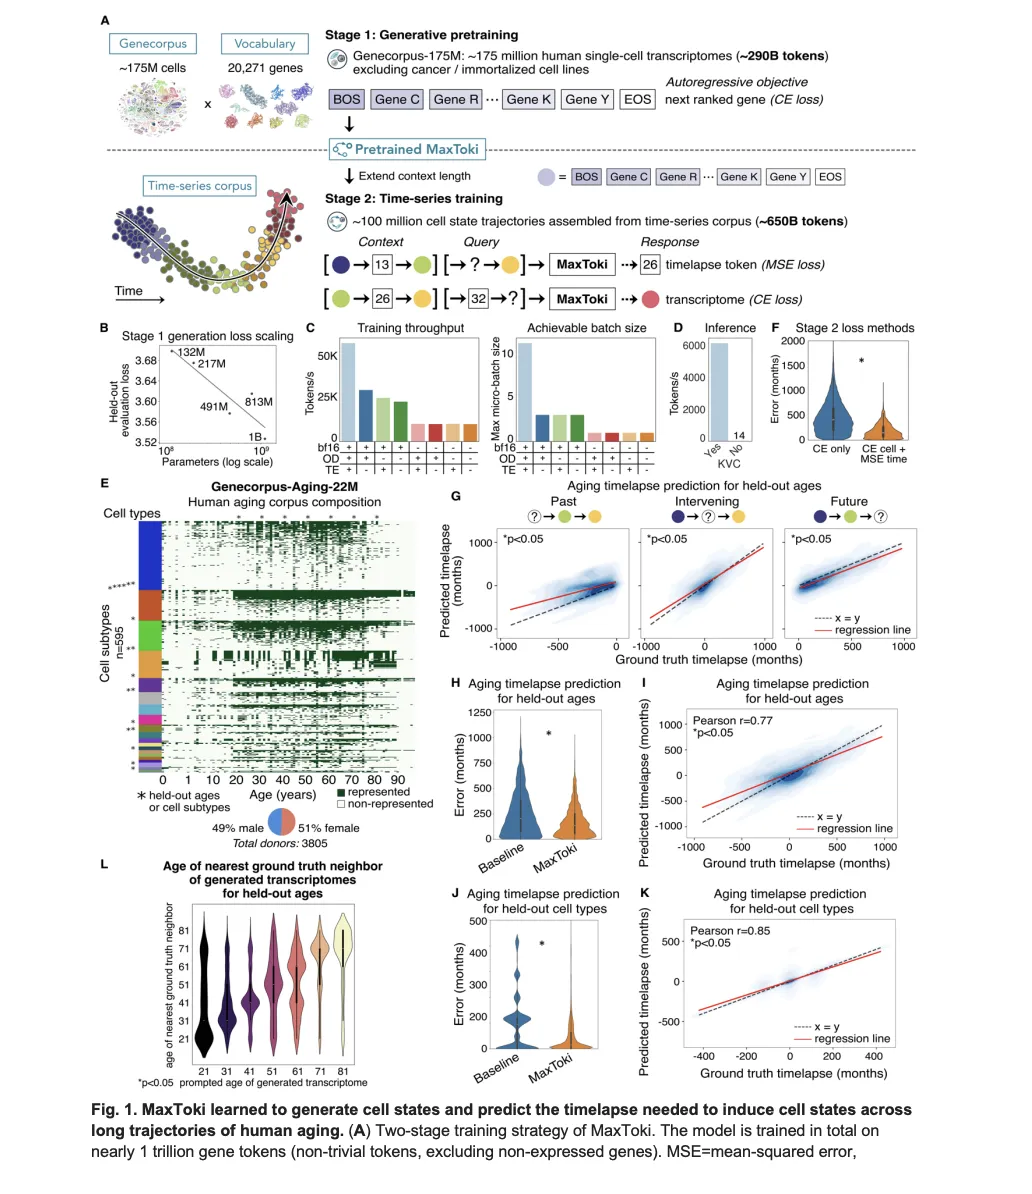
🧠MaxToki is a new AI foundation model that can predict cellular aging patterns and trajectories, addressing a key limitation in existing biological models that only analyze cells as static snapshots. The technology represents a significant advancement in computational biology by incorporating temporal dynamics into cellular analysis.
AIBullisharXiv – CS AI · Mar 315/10
AINeutralarXiv – CS AI · Mar 276/10
🧠Researchers introduce ReLope, a new routing method for multimodal large language models that uses KL-regularized LoRA probes and attention mechanisms to improve cost-performance balance. The method addresses the challenge of degraded probe performance when visual inputs are added to text-only LLMs.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers introduce RC2, a reinforcement learning framework that improves multimodal AI reasoning by enforcing consistency between visual and textual representations. The system uses cycle-consistent training to resolve internal conflicts between modalities, achieving up to 7.6 point improvements in reasoning accuracy without requiring additional labeled data.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers introduce TRAJEVAL, a diagnostic framework that breaks down AI code agent performance into three stages (search, read, edit) to identify specific failure points rather than just binary pass/fail outcomes. The framework analyzed 16,758 trajectories and found that real-time feedback based on trajectory signals improved state-of-the-art models by 2.2-4.6 percentage points while reducing costs by 20-31%.
🧠 GPT-5
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers introduce Experiential Reflective Learning (ERL), a framework that enables AI agents to improve performance by learning from past experiences and generating transferable heuristics. The method shows a 7.8% improvement in success rates on the Gaia2 benchmark compared to baseline approaches.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers introduce QuatRoPE, a novel positional embedding method that improves 3D spatial reasoning in Large Language Models by encoding object relations more efficiently. The method maintains linear scalability with the number of objects and preserves LLMs' original capabilities through the Isolated Gated RoPE Extension.
AINeutralarXiv – CS AI · Mar 276/10
🧠Researchers benchmarked 20 multimodal AI models on neuroimaging tasks using MRI and CT scans, finding that while technical attributes like imaging modality are nearly solved, diagnostic reasoning remains challenging. Gemini-2.5-Pro and GPT-5-Chat showed strongest diagnostic performance, while open-source MedGemma-1.5-4B demonstrated promising results under few-shot prompting.
🏢 Meta🧠 GPT-5🧠 Gemini
AINeutralarXiv – CS AI · Mar 276/10
🧠Researchers introduce a new nonparametric method called signed isotonic R² for efficiently detecting problematic items in AI benchmarks and assessments. The method outperforms traditional diagnostic techniques across major AI datasets including GSM8K and MMLU, offering a lightweight solution for improving evaluation quality.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers developed a framework using large language models (LLMs) as adaptive controllers for SIMP topology optimization, replacing fixed-schedule continuation with real-time parameter adjustments. The LLM agent achieved 5.7% to 18.1% better performance than baseline methods across multiple 2D and 3D engineering problems.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers developed SAVe, a self-supervised AI framework that detects audio-visual deepfakes by learning from authentic videos rather than synthetic ones. The system identifies visual artifacts and audio-visual misalignment patterns to detect manipulated content, showing strong cross-dataset generalization capabilities.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers developed lightweight generative AI models for creating synthetic network traffic data to address privacy concerns and data scarcity in network traffic classification. The models achieved up to 87% F1-score when classifiers were trained solely on synthetic data, with transformer-based approaches providing the best balance of accuracy and computational efficiency.
AINeutralarXiv – CS AI · Mar 276/10
🧠Researchers have developed TAAC, a framework for trustable audio-based depression diagnosis that protects user identity information while maintaining diagnostic accuracy. The system uses adversarial loss-based subspace decomposition to separate depression features from sensitive identity data, enabling secure AI-powered mental health screening.
AINeutralarXiv – CS AI · Mar 276/10
🧠A benchmarking study reveals demographic bias in multimodal large language models used for face verification, testing nine models across different ethnicity and gender groups. The research found that face-specialized models outperform general-purpose MLLMs, but accuracy doesn't correlate with fairness, and bias patterns differ from traditional face recognition systems.
🏢 Meta
AINeutralarXiv – CS AI · Mar 276/10
🧠Researchers evaluated whether large language models follow Occam's Razor principle when performing inductive and abductive reasoning, finding that while LLMs can handle simple scenarios, they struggle with complex world models and producing high-quality, simplified hypotheses. The study introduces a new framework for generating reasoning questions and an automated metric to assess hypothesis quality based on correctness and simplicity.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers developed UF-FGTG, a framework that automatically converts novice user prompts into model-preferred prompts for text-to-image AI systems. The system uses a novel Coarse-Fine Granularity Prompts dataset and achieved 5% improvement across quality metrics compared to existing methods.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers propose combining large language models (LLMs) with combinatorial inference to address hallucinations and improve structured prediction accuracy. The study finds that incorporating symbolic inference yields more consistent predictions than prompting alone, with calibration and fine-tuning further enhancing performance on complex tasks.
AINeutralarXiv – CS AI · Mar 276/10
🧠Researchers present a unified theoretical framework for understanding generative diffusion models by connecting information theory, dynamics, and thermodynamics. The study reveals that diffusion generation operates as controlled noise-induced symmetry breaking, where the score function regulates information flow from noise to structured data.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers introduce TimeLens, a family of multimodal large language models optimized for video temporal grounding that outperforms existing open-source models and even surpasses proprietary models like GPT-5 and Gemini-2.5-Flash. The work addresses critical data quality issues in existing benchmarks and introduces improved training datasets and algorithmic design principles.
🧠 GPT-5🧠 Gemini
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers propose TAG-MoE, a new framework that improves unified image generation and editing models by making AI routing decisions task-aware rather than task-agnostic. The system uses hierarchical task semantic annotation and predictive alignment regularization to reduce task interference and improve model performance.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers introduce ArtiAgent, an automated system that creates pairs of real and artifact-injected images to help AI models better detect and fix visual artifacts in generated content. The system uses three specialized agents to synthesize 100K annotated images, addressing the costly and scaling challenges of human-labeled artifact datasets.
AIBullisharXiv – CS AI · Mar 276/10
🧠Researchers introduced Graph-of-Mark (GoM), a new visual prompting technique that overlays scene graphs onto images to improve spatial reasoning in multimodal language models. Testing across 3 open-source MLMs and 4 datasets showed GoM improved zero-shot visual question answering and localization accuracy by up to 11 percentage points compared to existing methods like Set-of-Mark.
AI × CryptoBullishNewsBTC · Mar 276/10
🤖Bittensor (TAO) has surged 35% in the past week and 94% since March 8th, reaching the 27th largest cryptocurrency by market cap at $3.65 billion. Despite the strong price rally driven by AI narrative, social media sentiment remains mixed with the third-worst negative bias in six months, suggesting retail FOMO hasn't developed yet.
$BTC$DOGE$SUI🧠 DALL E