#machine-learning News & Analysis
Coverage of #machine-learning spans 2,608 indexed articles, with 262 pieces published in the last month. Recent discussion shows 55.7% bullish sentiment, though this represents a 5.3 percentage point decline from the previous quarter, suggesting a modest cooling in tone. Research publications dominate the discourse, particularly through arXiv's computer science and AI sections, while conversations frequently center on models and platforms including Llama, Meta, and Gemini.
Related coverage tends to intersect with #research, #ai-research, and #llm discussions. Scan the article list below to explore the latest developments and perspectives.
sentiment · last 30d (262 articles) · -5.3pp bullish vs prior 90dTop sources:arXiv – CS AI · 1922Apple Machine Learning · 14Crypto Briefing · 10MarkTechPost · 8Hugging Face Blog · 6
Most-discussed entities:Llama · 23Meta · 17Gemini · 15GPT-4 · 14GPT-5 · 13
AIBullisharXiv – CS AI · Jun 27/10
🧠FlowTime introduces a novel 'Continuous Generative Regression' paradigm for watch time prediction in short-video recommender systems, addressing limitations of existing regression, ordinal, and discrete generative approaches. The method uses flow-based personalized priors within a one-step generative VAE to model multimodal user-item interaction patterns while reducing inference latency, demonstrating superior performance in both offline experiments and A/B testing.
AIBullisharXiv – CS AI · Jun 27/10
🧠Researchers introduce AgentPLM, a protein language model enhanced with real-time biophysical feedback and tool integration to generate optimized protein sequences. The system combines reasoning-augmented decoding with a novel training approach, achieving state-of-the-art performance on enzyme design, antibody optimization, and structural stability tasks.
AIBullisharXiv – CS AI · Jun 27/10
🧠Researchers have developed a framework for generating high-quality synthetic data that enables Large Language Models to achieve predictable scaling laws for recommendation systems—a previously unattainable milestone. Models trained on this principled synthetic data outperform those trained on real user interaction data by 130% on key metrics, establishing a foundational methodology for scaling LLM capabilities in recommendations.
🏢 Perplexity
AIBullisharXiv – CS AI · Jun 27/10
🧠Researchers introduce DyLLM, a training-free inference framework that accelerates diffusion language model decoding by up to 9.6x by selectively computing only salient tokens rather than processing entire sequences at each step. The approach identifies important tokens through attention context similarity and reuses cached activations for stable tokens, maintaining baseline accuracy across benchmarks.
AIBullisharXiv – CS AI · Jun 27/10
🧠Researchers introduce Lodestar, a machine learning-based request routing system that dynamically assigns large language model inference tasks to GPU instances in distributed clusters. The system achieves up to 4.38x improvements in latency metrics compared to existing heuristics by continuously learning optimal routing strategies in real-time.
AIBullisharXiv – CS AI · Jun 27/10
🧠Researchers introduce Science Earth, a planet-scale operating system that enables diverse AI capabilities—from simulation clusters to wet-lab robots to proof engines—to autonomously discover, coordinate, and collaborate on scientific problems without pre-designed workflows. Two validation runs demonstrate the system successfully identifying theoretical gaps in mathematical models and generating novel insights from cancer cell data through distributed, self-correcting reasoning.
AIBullisharXiv – CS AI · Jun 27/10
🧠CRISP is an unsupervised machine learning framework that automates the analysis of multiple whole-slide images (WSIs) in digital pathology by selectively sampling informative patches across all slides in a case rather than relying on a single pathologist-selected slide. The approach matches or exceeds current clinical practice for breast cancer diagnosis and retrieval while eliminating subjective slide selection and reducing computational burden.
AIBullishArs Technica – AI · Jun 17/10
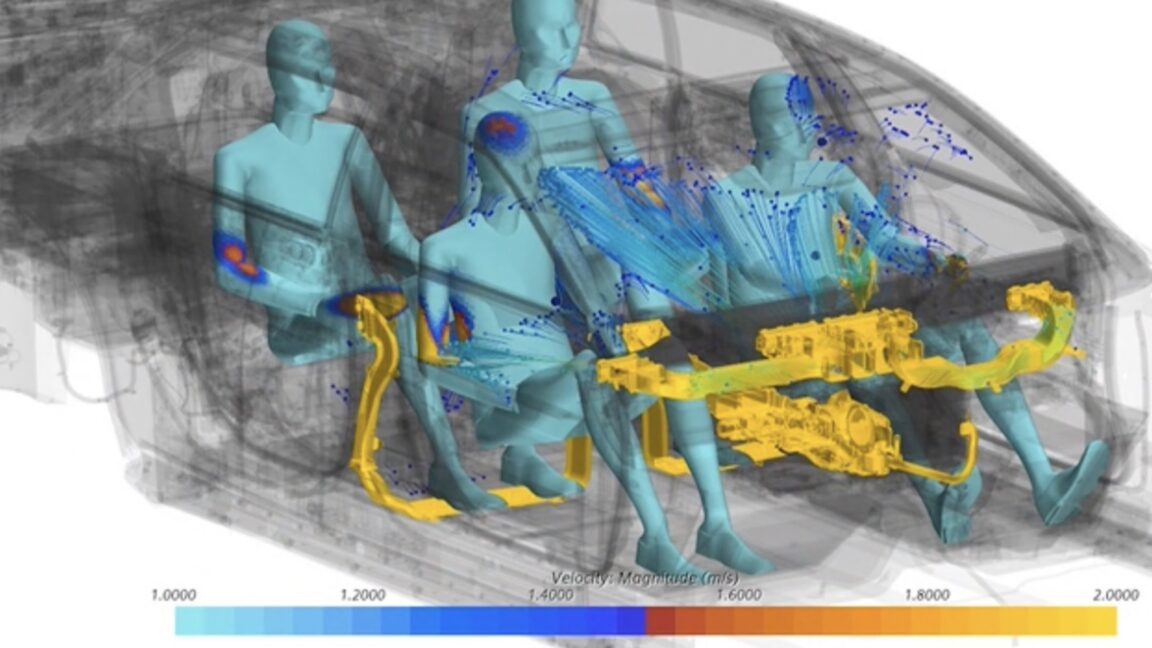
🧠General Motors is leveraging AI and machine learning to dramatically accelerate vehicle development cycles, reducing computational simulation time from 15 hours to one minute through advanced virtualization techniques including CFD, FEA, and digital twins. This technological shift demonstrates how AI adoption in traditional manufacturing can create substantial efficiency gains and competitive advantages in automotive design and production.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers introduce PRISM, a training-free framework for efficiently selecting visual instruction data for multimodal language models that reduces computational costs to 30% of conventional pipelines while improving performance across multiple benchmarks. The method addresses global semantic drift caused by anisotropic visual feature distributions, enabling more efficient model fine-tuning without sacrificing quality.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers have proven that Shapley values, a key framework for attribution in machine learning, depend exclusively on the odd component of set functions. This theoretical breakthrough justifies the effectiveness of paired sampling and enables OddSHAP, a new estimator that achieves state-of-the-art accuracy by performing regression solely on the odd subspace using Fourier basis decomposition.
AIBearisharXiv – CS AI · Jun 17/10
🧠Researchers propose Bayesian Membership Inference Attacks (BMIA), a novel method that uses Bayesian sampling and Laplace approximation to detect whether specific data points were used in model training. The approach significantly reduces computational overhead compared to existing methods while achieving state-of-the-art attack performance across image, text, and tabular datasets.
AIBullisharXiv – CS AI · Jun 17/10
🧠EchoRL introduces a novel technique to overcome learning signal collapse in reinforcement learning systems training large language models. By leveraging entropy patterns from expert trajectories to extract value from otherwise degenerated rollouts, the method achieves consistent performance improvements across multiple benchmarks and LLM architectures with minimal computational overhead.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers propose replacing the outdated point neuron model in artificial neural networks with a more biologically realistic cortical cell model, demonstrating improvements in expressivity, robustness, learning speed, and reduced memorization without increasing parameters. This fundamental advancement in neural architecture design could enhance AI system efficiency and performance across applications.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers introduce SHIELD, a novel machine learning framework that combines Interval Bound Propagation with hypernetwork architecture to achieve certifiably robust continual learning without replay buffers. The method uses task-specific embeddings and a new Interval MixUp training strategy to maintain security across sequential tasks while outperforming existing approaches on adversarial benchmarks.
AIBullisharXiv – CS AI · Jun 17/10
🧠A comprehensive survey examines the convergence of Graph Machine Learning and Large Language Models, exploring how LLMs can enhance graph neural networks while graphs provide factual knowledge to improve LLM reasoning and reduce hallucinations. This bidirectional relationship addresses key challenges in both domains, including data labeling, heterophily, and out-of-distribution generalization.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers introduce VLM3, a method that enables standard Vision Language Models to effectively learn 3D tasks through simple techniques like focal length unification and text-based pixel references, eliminating the need for complex task-specific architectures. The approach advances depth estimation accuracy and enables diverse 3D capabilities while maintaining standard VLM architecture, suggesting a paradigm shift toward simpler, more scalable 3D learning.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers have developed SWIM, a machine learning method for synthesizing physically realistic swimming animations from minimal training data. The approach enables AI systems to learn complex full-body swimming motions from a single example and generalize across different environments, body types, and swimming styles, addressing long-standing challenges in physics-based character animation.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers introduce Flow Equivariant World Models, a framework that uses time-parameterized symmetries to improve how AI systems predict dynamics in partially observed environments. The approach significantly outperforms existing diffusion and recurrent models by maintaining equivariant memory structures that track both observed and unobserved regions as they evolve over time.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers introduce MHLF, a multigrid-hierarchical deep learning framework that accelerates computational fluid dynamics simulations for full-scale 3D aircraft by 3-8x while maintaining high-fidelity accuracy across subsonic, transonic, and supersonic flight regimes. This breakthrough addresses a critical bottleneck in aerospace design by enabling practical full-flow-field prediction for engineering-scale aircraft, moving beyond previous limitations of 2D or simplified models.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers propose DeMix, a framework that uses model merging to efficiently determine optimal data mixtures for large language model pre-training without expensive repeated training cycles. The approach decouples the search process from training costs, enabling evaluation of multiple data combinations while also releasing a 22-token dataset to support open research.
AIBullisharXiv – CS AI · Jun 17/10
🧠RayDer introduces a unified transformer architecture that consolidates camera estimation, scene reconstruction, and rendering into a single model for self-supervised novel view synthesis from real-world video. The system achieves clean power-law scaling with data and compute while maintaining competitive performance with supervised approaches, addressing a key scalability challenge in 3D vision.
AIBullisharXiv – CS AI · Jun 17/10
🧠ProofWala is an open-source multilingual proof engineering framework that enables neural theorem proving across multiple interactive theorem provers like Lean 4 and Rocq through unified infrastructure. The framework demonstrates that cross-lingual training across different proof assistants improves performance on mathematical proof tasks, with significant gains shown in Lean Mathlib and domain-specific applications.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers introduce PENCIL, a plain Transformer model that outperforms Graph Neural Networks at link prediction by using attention over sampled local subgraphs instead of complex structural encodings. The approach demonstrates that simpler architectural choices can achieve superior performance while maintaining scalability and parameter efficiency, challenging the industry's reliance on elaborate engineering techniques.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers demonstrate that efficient LLM benchmarking can be substantially improved by treating it as a multiple regression problem with kernel ridge regression and applying minimum redundancy maximum relevance (mRMR) feature selection. The approach achieves lower prediction errors and faster computation than existing methods while maintaining consistency across different data splits.
AIBullisharXiv – CS AI · Jun 17/10
🧠Researchers introduce Clean-PR, a training methodology that leverages 2 million real-world GitHub pull requests to improve AI models' ability to perform repository-level code editing. The approach achieves significant performance gains on SWE-bench benchmarks without relying on complex agent scaffolding, demonstrating that code editing capabilities can be effectively internalized into model weights through high-quality training signals.