#neural-networks News & Analysis
Recent coverage of #neural-networks spans 385 indexed articles, with 70 published in the past month. The discussion involves significant research output, particularly from arXiv's computer science and AI sections, alongside analysis from crypto and technology outlets. Perplexity, Llama, and Nvidia emerge as the most frequently mentioned entities in this coverage.
Sentiment around the topic has softened over the past 30 days, with bullish commentary declining 18.2 percentage points from the previous quarter. Currently, 31.4% of recent articles adopt a bullish tone, while 58.6% remain neutral and 10% bearish. Scan the articles below to explore the latest developments and perspectives.
sentiment · last 30d (70 articles) · -18.2pp bullish vs prior 90dTop sources:arXiv – CS AI · 330Crypto Briefing · 2MarkTechPost · 2Apple Machine Learning · 2Decrypt · 1
Most-discussed entities:Perplexity · 9Llama · 7Nvidia · 3Gemini · 2
AINeutralarXiv – CS AI · Jun 46/10
🧠Researchers introduce MaskAQ, a novel data-free quantization technique for Vision Transformers that identifies and aligns informative image regions to improve model compression without requiring access to real training data. The approach addresses distribution mismatches in synthetic data generation, enabling more efficient deployment of ViT models while maintaining security and privacy.
AINeutralarXiv – CS AI · Jun 46/10
🧠Researchers propose Low-Rank Decay (LRD), a spectral regularization technique that improves generalization in scale-invariant Transformer architectures by compressing weight singular values after memorization. Unlike standard L2 decay, LRD remains effective in normalized models and accelerates grokking—the delayed generalization phenomenon—on algorithmic tasks.
$UV
AINeutralarXiv – CS AI · Jun 46/10
🧠A research study empirically examines how data scale, model complexity, and input modalities affect visual generalization in deep neural networks using CIFAR-10/100 datasets. The findings reveal that increasing training data consistently improves generalization, while model complexity changes yield inconsistent results, and color information removal significantly degrades performance.
AINeutralarXiv – CS AI · Jun 45/10
🧠Researchers introduce SFMambaNet, a novel deep learning architecture that combines spectral-frequency analysis with Mamba-based state space models to improve correspondence pruning—the task of filtering accurate feature matches from noisy initial sets. The method outperforms existing Graph Neural Network approaches by integrating frequency domain perception to better distinguish valid correspondences from outliers.
AINeutralarXiv – CS AI · Jun 46/10
🧠Researchers introduce CHASMBrain, a hierarchical neural architecture using Mamba models to predict brain activity from images by mimicking the visual cortex's functional organization. The model achieves state-of-the-art performance on brain imaging datasets and reveals that different neural pathways specialize in processing semantic versus spatial information, advancing understanding of how artificial and biological vision systems align.
AINeutralarXiv – CS AI · Jun 46/10
🧠Researchers introduce BabyCL, a continual multimodal learning framework that trains neural networks on egocentric video data in a single chronological pass, mimicking how children actually learn language. The approach outperforms streaming baselines on word-referent mapping tasks while substantially closing the gap to offline training methods.
AINeutralarXiv – CS AI · Jun 45/10
🧠Researchers propose MC-PSO and MC-APSO, novel parallel neural network architectures that combine multi-column radial basis function networks with particle swarm optimization algorithms. These methods outperform existing approaches in accuracy, recall, and computational efficiency on benchmark datasets by distributing training across spatial subsets.
AINeutralarXiv – CS AI · Jun 46/10
🧠Researchers introduce MesaNet, an improved recurrent neural network architecture that optimizes sequence modeling through test-time training, achieving better language modeling performance than previous RNNs while requiring additional inference-time compute. The work advances the trend toward linearized transformers that maintain constant memory costs during inference, positioning computational efficiency against performance gains.
🏢 Perplexity
AINeutralarXiv – CS AI · Jun 46/10
🧠Researchers introduce ClustRecNet, a deep learning framework that automatically recommends optimal clustering algorithms for datasets by learning from 34,000 synthetic examples. The system outperforms traditional validity indices and AutoML approaches, achieving 44% improvement over leading competitors on real-world benchmarks.
AINeutralarXiv – CS AI · Jun 46/10
🧠Researchers demonstrate that Masked Diffusion Language Models fundamentally alter neural network learning dynamics on the k-parity problem, eliminating the typical grokking phenomenon and enabling faster generalization. By decomposing the MD objective into signal and noise regimes, they optimize mask probability distribution, achieving up to 8.8% performance improvements on 50M-parameter models and 5.8% gains on 8B-parameter models.
🏢 Perplexity
AIBullisharXiv – CS AI · Jun 46/10
🧠Researchers introduce DSL-Topic, a novel framework that improves neural topic modeling by distilling soft labels from language models rather than relying on traditional bag-of-words reconstruction. The approach leverages LM-generated contextual signals to produce higher-quality topics with better coherence and semantic alignment, demonstrating significant improvements over existing baselines.
AIBullishMIT News – AI · Jun 36/10
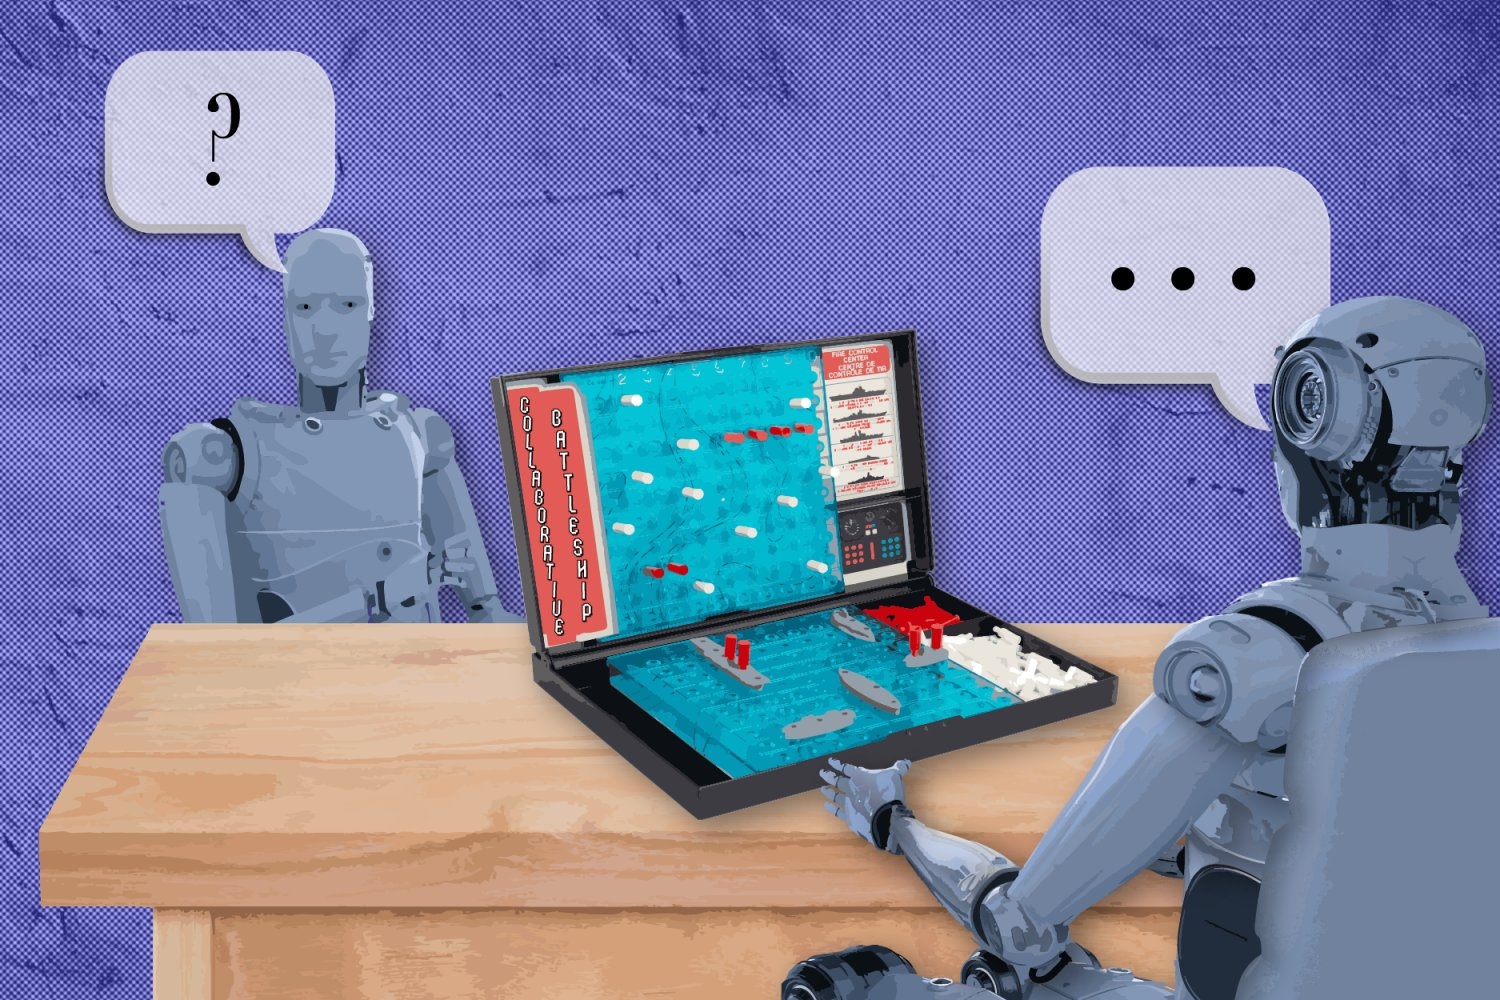
🧠MIT researchers demonstrated that smaller AI models can outperform larger ones at asking strategic questions by using the classic game Battleship as a training framework. The findings suggest that efficient questioning strategies could reduce AI inference costs by up to 99 percent while improving performance.
AINeutralarXiv – CS AI · Jun 35/10
🧠Researchers compared Transformer and LSTM neural network architectures for predicting streamflow in ungauged watersheds using data from NOAA's National Water Model. The study found that LSTM models outperformed Transformer models for upstream streamflow inference, though incorporating downstream hydrologic information improved performance across all architectures by over 60%.
AINeutralarXiv – CS AI · Jun 35/10
🧠Researchers introduce RelGT-AC, a machine learning architecture that improves autocomplete predictions in relational databases by combining graph transformers with specialized techniques for handling multi-table data. The model demonstrates superior performance on real-world database tasks, particularly for text-heavy applications, advancing practical machine learning capabilities for enterprise systems.
AIBullisharXiv – CS AI · Jun 26/10
🧠RefDiffNet introduces a lightweight neural network module that enhances PCB defect detection by comparing defective images against reference images, improving detection accuracy by up to 18% while adding minimal computational overhead. The plug-and-play approach works across multiple detector architectures, bridging classical inspection techniques with modern deep learning.
AIBullisharXiv – CS AI · Jun 26/10
🧠Researchers propose Morlet Spectral Transformer (MST), a novel neural network architecture for detecting emotions from EEG brain signals across different subjects. The method outperforms larger pretrained models by using specialized wavelet-based signal processing and frequency-specific spatial analysis, demonstrating that intelligent representation design can replace computationally expensive pretraining approaches.
AINeutralarXiv – CS AI · Jun 26/10
🧠Researchers developed a method combining multi-agent deep reinforcement learning with explainable AI techniques to optimize drag reduction in turbulent flows, achieving 34.44% drag reduction with only 0.43% energy input—significantly outperforming traditional opposition control methods.
AINeutralarXiv – CS AI · Jun 26/10
🧠Researchers propose DART, a test-time training method that improves dense retrieval reranking without requiring labeled data. By adapting scoring functions at inference time using pseudo-labels from document rankings, DART achieves 2.1% NDCG improvements across BEIR benchmarks with minimal latency overhead, addressing a key limitation in zero-resource information retrieval systems.
AINeutralarXiv – CS AI · Jun 26/10
🧠Researchers propose MViewRouter, a deep reinforcement learning framework that solves combinatorial routing problems like TSP and CVRP by embedding geometric symmetries directly into the model architecture rather than relying on data augmentation. The approach uses multi-view alternating attention and collective policy gradient aggregation to achieve more consistent decision-making and improved generalization across problem variants.
AINeutralarXiv – CS AI · Jun 26/10
🧠Researchers introduce Soft-NBCE, an improved method for processing ultra-long text contexts in large language models by replacing discrete chunk selection with weighted chunk fusion. The approach demonstrates measurable improvements on multi-hop reasoning tasks while maintaining efficient memory usage, addressing a critical bottleneck in LLM inference.
AINeutralarXiv – CS AI · Jun 26/10
🧠Researchers introduce BRo-JEPA, a neural network architecture that learns modular arithmetic rules by imposing circular structure in latent space, achieving 99.46% zero-shot generalization on unseen operations. The work demonstrates that neural networks can learn abstract algebraic rules rather than merely memorizing patterns when architecture aligns with problem structure.
AIBullisharXiv – CS AI · Jun 26/10
🧠Researchers introduce UR-JEPA, a novel regularization technique for Joint-Embedding Predictive Architectures that addresses representation collapse by targeting uniformly rectifiable measures rather than isotropic Gaussians. The method demonstrates superior performance on Inet10 with an 0.83 percentage-point gain over existing approaches and produces geometrically distinct embeddings with sharper spectral drops, suggesting more structured learned representations.
AINeutralarXiv – CS AI · Jun 26/10
🧠Researchers successfully deployed a physics foundation model trained on simulations to predict laboratory turbulence behavior, achieving zero-shot generalization to experimental data without direct exposure to lab conditions. The model resolved a decades-old discrepancy between simulated and experimental Rayleigh-Taylor instability measurements, suggesting initial conditions—not fundamental physics—explain the sim-experiment gap.
AINeutralarXiv – CS AI · Jun 26/10
🧠Researchers propose GJDNet, a robust Graph Neural Network defense framework that protects against adversarial attacks by jointly disentangling node representations and decision spaces. The approach addresses vulnerabilities in GNNs caused by adversarial perturbations that invert graph connectivity patterns, achieving improved robustness across different graph types.
AIBullisharXiv – CS AI · Jun 26/10
🧠Researchers introduce TDPM, a novel generative recommendation framework that applies time-aware diffusion models to improve personalized item suggestions by distinguishing between long-term period preferences and short-term event-triggered preferences. The approach achieves significant performance improvements of up to 29.21% in Hit Rate and 25.45% in NDCG metrics compared to existing methods.